
Can No-Code Bioinformatics Replace Coding? Here’s Where It Helps
Working with sequencing data can get complicated quickly. One experiment may involve quality control, data processing, statistical analysis, and visualization before researchers can start interpreting the results. For many scientists, the challenge is not just understanding the biology. It is also finding the right tools and managing the entire analysis workflow.
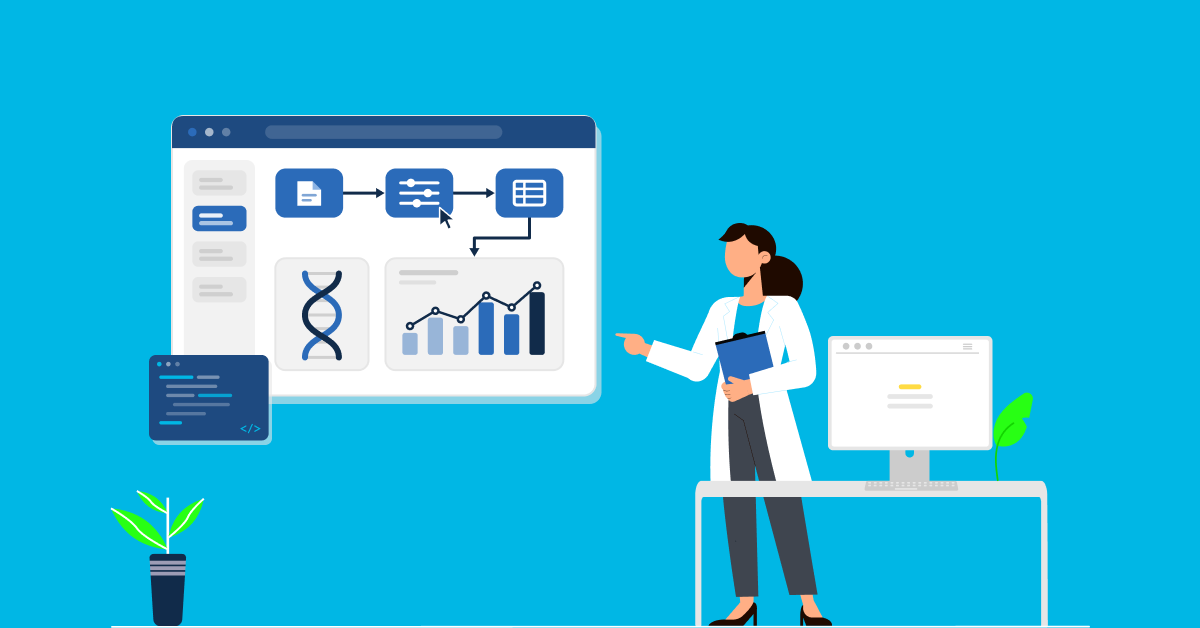
This is where no-code bioinformatics comes in.
Instead of writing scripts for every analytical step, researchers can use graphical interfaces and predefined pipelines to perform many routine tasks. But does that mean coding is no longer necessary in bioinformatics?
Not quite. No-code tools can make data analysis easier, but knowing when to use them and when coding is still needed makes all the difference.
What Is No-Code Bioinformatics?
No-code bioinformatics allows researchers to analyze biological data using graphical interfaces, automated workflows, and predefined tools without manually writing code for every step.
For example, a researcher working with RNA sequencing data may need to assess data quality, quantify gene expression, identify differentially expressed genes, and generate visualizations.
With a suitable no-code bioinformatics platform, these steps can be organized into a structured pipeline. Researchers can upload their data, select the appropriate workflow, configure available parameters, and review the results.
The benefit is simple: less time spent managing repetitive technical tasks and more time available to focus on the research question.
Where Does No-Code Bioinformatics Actually Help?
No-code bioinformatics is especially useful when researchers need to run established workflows or repeat similar analyses across multiple datasets.
1. Simplifying NGS Data Analysis
Next-generation sequencing (NGS) generates large amounts of data that require careful processing before researchers can interpret the results.
A typical workflow may involve quality control, read alignment or quantification, variant calling, statistical analysis, and visualization.
NGS data analysis tools with automated pipelines can bring these steps together, reducing the need to configure every tool manually.
For routine projects, this can make the workflow easier to manage. Researchers still need to check data quality, choose appropriate settings, and confirm that the pipeline matches their experimental requirements.
2. Making Gene Expression Analysis More Accessible
Bulk RNA sequencing helps researchers understand how gene expression changes across conditions, treatments, or experimental groups.
However, moving from raw sequencing data to meaningful results involves several analytical steps.
A no-code bioinformatics workflow can help researchers perform tasks such as:
- Quality assessment and expression quantification
- Differential gene expression analysis
- Identification of differentially expressed genes (DEGs)
- Visualization using PCA plots, heatmaps, and volcano plots
- Functional enrichment analysis, where supported
For teams working with multiple RNA-seq datasets, automated workflows can simplify repeated analysis and help maintain consistent processing settings.
Researchers can then spend more time investigating what the results mean biologically.
3. Reducing Repetitive Work Across Samples
Imagine a research team processing sequencing data from several experiments. If every dataset requires the same manual setup, the process can become time-consuming.
Bioinformatics workflow automation helps make repeated analysis more manageable. Once a suitable pipeline is established, it can be reused for compatible datasets rather than rebuilt from scratch each time.
This is particularly helpful for laboratories handling recurring batches of samples or working with limited computational resources.
However, reusing a pipeline does not automatically guarantee accurate results. Each dataset still needs appropriate quality checks, and researchers must confirm that the workflow and parameters suit the experiment.
4. Helping Researchers Who Do Not Code
Not every biologist or laboratory researcher has experience with Python, R, or command-line tools. That should not prevent them from accessing established computational methods.
A graphical interface can make common analytical tasks easier to navigate, especially for researchers who understand their experimental data but have limited programming experience.
No-code bioinformatics can therefore lower the technical barrier to routine analysis. It does not remove the need for statistical knowledge or biological expertise, but it can make the tools themselves more accessible.
So, Can No-Code Bioinformatics Replace Coding?
The answer depends on what you need to accomplish.
For standard workflows, no-code tools may provide everything required. But when a project needs a custom algorithm, an unusual statistical method, or a specialized data-processing step, programming can still be essential.
Here is a simple comparison:
| Research requirement | No-code tools | Coding-based approach |
|---|---|---|
| Running established pipelines | Often a good fit | Also suitable |
| Repeating routine analysis | Can simplify the process | Offers automation and control |
| Custom analytical methods | Depends on available features | Greater flexibility |
| Working with unusual data formats | Depends on platform support | More adaptable |
| Developing new bioinformatics tools | Usually limited | Often essential |
The two approaches are not competitors in every situation. Many research teams can use automated pipelines for routine tasks while relying on coding for specialized analysis and workflow customization.
If choosing the right software feels like another research challenge, this related article explains how to choose the right bioinformatics tools for your analysis.
What Should You Consider Before Choosing a No-Code Platform?
Before adopting a no-code bioinformatics platform, look beyond how easy it is to use.
Consider whether it supports your data type, provides the analytical methods your study requires, and allows you to configure relevant parameters. Check how results are presented and whether you can access the outputs needed for further analysis.
Reproducibility also matters. Reliable workflows should make it possible to track relevant settings, software versions, and reference resources.
For sensitive sequencing data, review the platform's security measures, access controls, and data retention policies before uploading files.
Most importantly, remember that automated analysis still requires scientific judgment. A pipeline can process data, but researchers must assess the quality of the results and determine whether the findings support their research questions.
How GenomeBeans Fits Into the No-Code Bioinformatics Workflow
For researchers looking to simplify routine sequencing analysis, GenomeBeans offers an online bioinformatics platform with automated pipelines for supported NGS workflows.
Its capabilities include bulk transcriptomics, single-cell transcriptomics, variant calling, and metagenomics analysis. These workflows help researchers access relevant analytical processes through an online environment without having to manually coordinate every step.
For example, researchers working on gene expression studies can explore the GenomeBeans bulk transcriptomics pipeline to learn more about the available analysis workflow.
GenomeBeans also offers bioinformatics services and research consulting for projects that need additional analytical support.
The aim is not to eliminate coding. It is to make established workflows more accessible and help research teams spend less time on repetitive processing and more time understanding their data.
Final Thoughts
No-code bioinformatics is making routine sequencing analysis more accessible to researchers who want to work efficiently without writing code for every analytical step.
It can simplify established pipelines, support repeated analyses, and reduce some of the technical barriers associated with NGS data analysis. At the same time, coding remains valuable for custom methods, complex workflows, and specialized research questions.
The best approach is not to choose between no-code tools and coding blindly. It is to use the approach that fits your data, your research question, and your analytical needs.
When the right tools and scientific expertise work together, bioinformatics workflows can become more manageable, reproducible, and useful for research.
Popular Post
-
12 October 2026
Bioinformatics Tools Are Everywhere. Knowing Which One to Use Is the Hard Part
-
05 October 2026
Bioinformatics vs Data Science: What’s Actually Different?
-
28 September 2026
How Scientists Use Bulk Transcriptomics to Understand What a Drug Does Inside Cells
-
21 September 2026
Inside a Brain, Cell by Cell: What Alzheimer's Research Looks Like at Single-Cell Resolution
-
14 September 2026
When Mitochondria Fail: How Variant Calling Supports Mitochondrial Disease Research